Logo
DevOpsLens
Dark server room with glowing rack lights and dual monitor setup showing terminal output and Grafana dashboards in indigo light
FRAME_001 ◈ 2026
◈ Platform & DevOps Engineering ◈

The invisible work
that keeps you live.

Kubernetes migrations. CI/CD from scratch. 3 a.m. incidents that flattened back to green before anyone woke up.

SCROLL TO ADVANCE FRAMES
AVAILABLE FOR CONTRACT
Kiran Mehta
SENIOR PLATFORM ENGINEER · REMOTE · km@devopslens.io
7+
YRS EXP
23
K8S CLUSTERS
99.97%
SLA MET
◈ Case Studies

Proof, not promises.

Drag or swipe to advance frames. Each project is three panels: before, work, outcome.

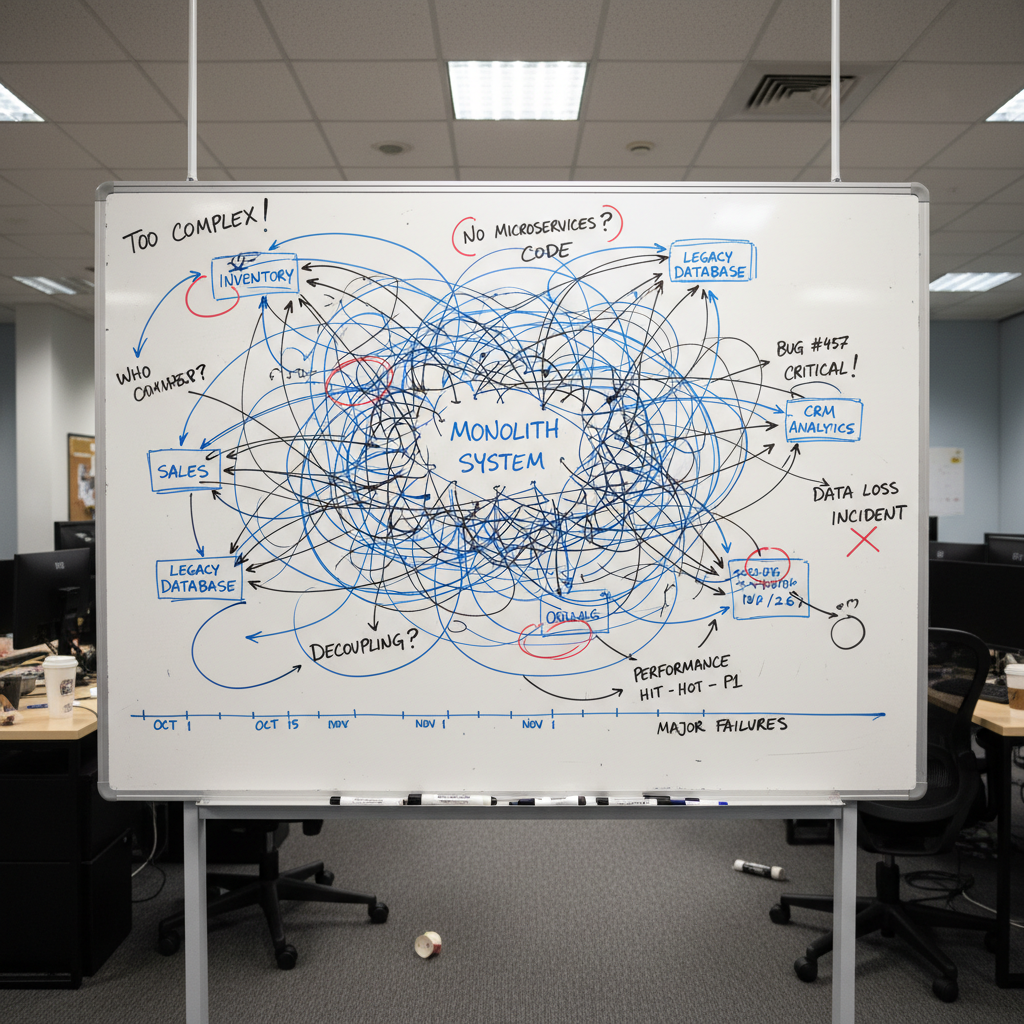
Whiteboard architecture diagram showing tangled monolith system with handwritten notes and incident tracking marks
THE BEFORE
FinTrack Labs
Monolith → Kubernetes Migration
Q1–Q3 2025 · 8 months

A 6-year-old Rails monolith running on bare EC2 instances. Capistrano deploys that routinely failed silently. No health checks, no circuit breakers, no distributed tracing. The on-call rotation was a 3-person nightmare.

Deploy frequency
2× / month
Deploy duration
47 min avg
Incidents / month
11
MTTR
3h 20m
The Work

Terraform, Helm, ArgoCD, and 8 months of unglamorous wiring.

◈ Cluster Topology
ALB
Ingress
ArgoCD
API
Worker
Cron
RDS
Redis
S3
▶terraform · infrastructure
main.tf
# eks-cluster.tf — Production clusterresource "aws_eks_cluster" "fintrack_prod" {  name     = "fintrack-prod-v2"  role_arn = aws_iam_role.eks_master.arn  version  = "1.28"  vpc_config {    subnet_ids              = module.vpc.private_subnets    endpoint_private_access = true    endpoint_public_access  = false    security_group_ids      = [aws_security_group.eks_control.id]  }  enabled_cluster_log_types = [    "api", "audit", "authenticator"  ]}# Blue-green node groups for zero-downtime rotationresource "aws_eks_node_group" "blue" {  cluster_name    = aws_eks_cluster.fintrack_prod.name  node_group_name = "prod-blue"  instance_types  = ["t3.xlarge"]    scaling_config {    desired_size = 4    max_size     = 12    min_size     = 2  }}
▶github actions · deploy pipeline
deploy.yml
# .github/workflows/deploy.ymlname: Deploy → Productionon:  push:    branches: [main]jobs:  build-and-push:    runs-on: ubuntu-latest    steps:      - uses: actions/checkout@v4            - name: Build & push image        run: |          docker build -t $ECR_REPO:$GITHUB_SHA .          aws ecr get-login-password | docker login --username AWS \            --password-stdin $ECR_REPO          docker push $ECR_REPO:$GITHUB_SHA  deploy:    needs: build-and-push    steps:      - name: ArgoCD sync        run: |          argocd app sync fintrack-prod \            --revision $GITHUB_SHA \            --timeout 300            - name: Smoke test        run: ./scripts/smoke-test.sh $DEPLOY_URL
The After
LIVE DATA

Real numbers from Datadog. 90-day post-migration window.

Incident Rate (90 days)↓ Trending
Deploy frequency
2× / month→14× / week
+700%
Deploy duration
47 min→4m 12s
-91%
MTTR
3h 20m→3m 48s
-98%
Monthly incidents
11→1.4 avg
-87%
SLA achievement
96.2%→99.97%
+3.77pp
"
Kiran migrated our entire infrastructure in 8 months with zero customer-facing downtime. I've worked with 4 platform engineers over 6 years. None of them shipped at this quality.
Priya Krishnamurthy
VP Engineering, FinTrack Labs
Dark office with developer looking at terminal screen showing SSH commands and manual deployment logs
THE BEFORE
Claros Health
CI/CD Design from Scratch
Q4 2024 · 3 months

A Series A health-tech startup with 12 engineers, all deploying manually. No test automation, no staging parity, no artifact versioning. The CTO had stopped sleeping the night before every release.

Deploy method
Manual SSH
Staging lag
4–6 days
Rollback time
>45 min
Test coverage
0%
The Work

GitHub Actions, Terraform Cloud, Playwright E2E, and a staged rollout strategy.

◈ Cluster Topology
GitHub
Actions
Tests
ECR
Canary
Staging
Prod
DD
PagerDuty
▶terraform · infrastructure
main.tf
# pipeline-foundation.tfmodule "ci_runner_fleet" {  source = "./modules/github-runners"    runner_count   = 4  instance_type  = "c6a.2xlarge"  spot_enabled   = true  spot_max_price = "0.12"    labels = ["self-hosted", "linux", "x64", "production"]    autoscaling = {    min     = 2    max     = 8    scale_in_cooldown  = 300    scale_out_cooldown = 60  }}# Artifact registry with lifecycle policiesresource "aws_ecr_repository" "services" {  for_each = toset(var.service_names)  name     = "claros/${each.key}"    image_scanning_configuration {    scan_on_push = true  }}
▶github actions · deploy pipeline
deploy.yml
# Staged rollout with canary analysisdeploy:  strategy: canary  steps:    - name: Deploy 5% canary      run: kubectl set image deploy/api \        api=$IMAGE:$TAG          - name: Analyze canary (10 min)      uses: datadog/synthetics-action@v1      with:        api_key: ${{ secrets.DD_API_KEY }}        test_ids: "abc-123,def-456"            - name: Promote to 100%      if: steps.canary.outputs.passed == 'true'      run: |        kubectl annotate deploy/api \          kubernetes.io/change-cause="$TAG"        kubectl rollout status deploy/api
The After
LIVE DATA

Measured over 60 days post-implementation.

Incident Rate (90 days)↓ Trending
Deploy frequency
1× / 5 days→3× / day
+1400%
Staging lag
4–6 days→8 minutes
-99%
Rollback time
>45 min→90 seconds
-97%
Test coverage
0%→74%
+74pp
Release confidence
Low→High
CTO sleeps
"
Three months. He designed the entire pipeline, trained the team, and handed over documentation that our junior engineers can actually read. The before and after is embarrassing.
Marcus Webb
CTO, Claros Health
← drag to scrub timeline →
◈ Stack & Capabilities

The tools that earned
those metrics.

7 years of production scars. Not certifications — deployments, incidents, and postmortems.

Container Orchestration
KubernetesHelmArgoCDFluxKustomize
PROFICIENCY98%
Infrastructure as Code
TerraformPulumiAnsiblePacker
PROFICIENCY96%
CI/CD
GitHub ActionsGitLab CICircleCIJenkinsBuildkite
PROFICIENCY97%
Cloud Platforms
AWSGCPAzure
PROFICIENCY94%
Observability
DatadogGrafanaPrometheusJaegerPagerDuty
PROFICIENCY95%
Security & Compliance
VaultSOPSOPAFalcoTrivy
PROFICIENCY88%
Scripting & Automation
BashPythonGoRuby
PROFICIENCY91%
Certifications:CKACKADCKSAWS Solutions Architect ProHashiCorp Terraform Associate
◈ Signal Metrics · Aggregate

Numbers that don't need
a marketing team.

0
Kubernetes Clusters
Designed & operated in production
0%
Avg Deploy Time Reduction
Across all CI/CD engagements
0.00%
SLA Achievement
Measured over trailing 12 months
0m 48s
Best MTTR Achieved
Down from 3h 20m at FinTrack
0
Customer-Facing Outages
During any migration engagement
0+
Years Production Experience
Series A through Series D environments
All metrics sourced from client Datadog/Grafana exports. Available on request.
◈ Selectively taking contracts · Q2 2026

Your infrastructure
deserves this level of care.

Whether you need a Kubernetes migration, a CI/CD rebuild from scratch, or someone to own your platform engineering for 6 months — let's find out if we're the right fit.

km@devopslens.io
✓ NDA on request✓ References available✓ Remote-first✓ US timezone compatible